GraphRAG Processing Flow
GraphRAG processing has two stages: graph creation and query retrieval. Graph creation prepares source documents for retrieval. Query retrieval uses the knowledge graph and vector indexes to find relevant information and return context or generate an answer.
You can perform the graph creation and query retrieval operations described in this section by using the DBMS_AI_GRAPHRAG PL/SQL APIs. For information about using these APIs, see DBMS_AI_GRAPHRAG.
Graph Creation
During graph creation, GraphRAG processes source documents to extract entities and relationships and build a knowledge graph. It also creates embeddings and vector indexes to support retrieval.
Use the DBMS_AI_GRAPHRAG.CREATE_KNOWLEDGE_GRAPH procedure to perform these operations. For syntax and usage, see CREATE_KNOWLEDGE_GRAPH.
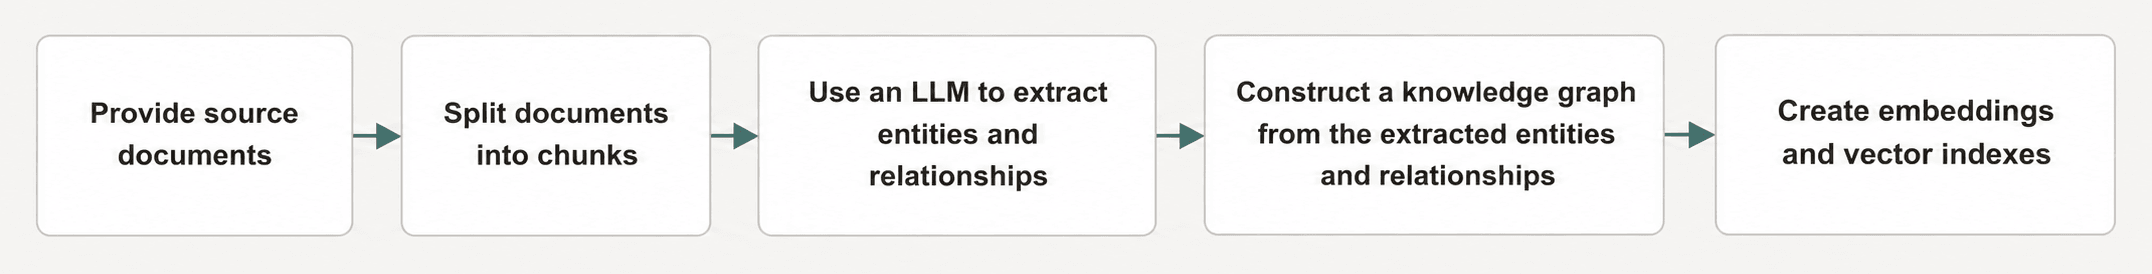
The graph creation phase prepares the source data for retrieval.
Prepare Documents
GraphRAG reads documents from a source table and text column. The source documents must be provided in plain-text format. Large documents are divided into chunks so that the text can be processed by language models and embedding models.
Chunking can affect retrieval quality. Small chunks can separate related facts, while large chunks can reduce precision or exceed model limits.
To add another source to an existing knowledge graph, use ADD_SOURCE. To remove a source from a knowledge graph, use REMOVE_SOURCE.
Extract Entities and Relationships
Each chunk is processed by a language model. The model extracts entities and relationships and returns the results in structured JSON.
Structured JSON allows the database to parse and store the extraction results more reliably than free-form text.
For example, the following facts can be extracted:
- Entity: Young Man Luther
- Entity: Erik Erikson
- Relationship: Young Man Luther was written by Erik Erikson
- Entity: Joan Erikson
- Relationship: Erik Erikson is the spouse of Joan Erikson
Construct the Knowledge Graph
The extracted entities become graph nodes. Relationships become edges between nodes. Chunks remain associated with the entities and relationships that were extracted from them.
The resulting graph preserves connections that may not be visible when documents are treated only as independent chunks.
Summarize Graph Components
For textual graphs, generate descriptions for entities and relationships. When a component has multiple descriptions, the LLM can summarize them if they exceed the configured limit. Non-textual graphs do not use this summarization step.
Create Embeddings and Vector Indexes
GraphRAG creates embeddings for the chunks and graph components used in retrieval. Embeddings are numerical representations that allow vector search to find information with a meaning similar to a user’s question.
For information about generating vector embeddings, see Generate Vector Embeddings.
GraphRAG then creates vector indexes to support efficient similarity searches. At query time, these searches identify relevant starting points for graph traversal.
For information about indexes that accelerate vector similarity searches, see Create Vector Indexes and Hybrid Vector Indexes.
Maintain the Graph
After graph creation, GraphRAG can maintain the graph as source data changes. When DML maintenance is enabled, changes to source records are queued and processed asynchronously.
GraphRAG updates the affected graph components rather than rebuilding the entire graph. For example, a change to Chunk C2 can cause the associated entities and relationships to be reprocessed. The graph can temporarily lag behind the source data while these changes are processed.
To check the status of a knowledge graph, use GET_KNOWLEDGE_GRAPH_STATUS.
If entity and relationship extraction, summary generation, embedding generation, or processing queued source-data changes fails, GraphRAG can queue an asynchronous retry for the failed task. For more details, see RECOVER_KNOWLEDGE_GRAPH.
Query Retrieval
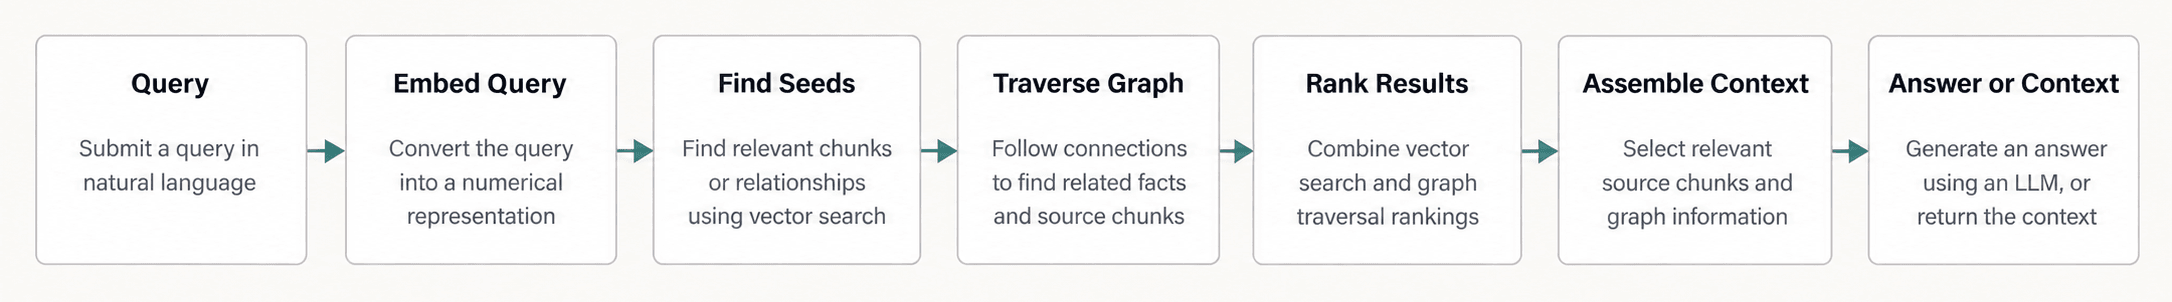
The query retrieval phase uses the graph to assemble information for a user question.
Use the DBMS_AI_GRAPHRAG.QUERY_KNOWLEDGE_GRAPH function to retrieve context and optionally generate an answer. For syntax and usage, see QUERY_KNOWLEDGE_GRAPH.
Embed the Query
The user question is converted into an embedding using the configured embedding model. The query embedding is compared with embeddings stored for chunks and graph components.
Discover Seed Nodes
Vector similarity search identifies relevant chunks or relationships as starting points for graph retrieval. These initial results are called seeds. The number of seeds controls the initial search scope. Seeds provide starting points for finding additional relevant information; they do not necessarily contain the answer.
Traverse the Graph
GraphRAG expands retrieval from the seed results by following connections in the knowledge graph. This can retrieve related entities, relationships, and supporting chunks that vector search alone might not find, bringing together facts from different chunks.
For example, to answer “Who is the spouse of the author of Young Man Luther?”, retrieval can find one chunk stating that Erik Erikson wrote the book. Graph traversal follows the connection from the book to Erik Erikson, then follows the connection from Erik Erikson to Joan Erikson. A second chunk identifies Joan as Erik Erikson’s wife. Together, these facts show that Joan Erikson is the spouse of the book’s author.
Rank the Results
GraphRAG ranks retrieved information according to the selected search type:
- VECTOR: Retrieves and ranks information directly by vector similarity to the query.
- GRAPH: Uses vector similarity to identify seed results, then follows graph connections and ranks information using scores propagated from the seeds.
- HYBRID: Combines the rankings from graph retrieval and direct vector search using Reciprocal Rank Fusion (RRF). Information retrieved by either method can contribute to the final results.
For an example of RRF applied to keyword and vector search results, see Understand Hybrid Search.
Construct the Context
The highest-ranked chunks, entities, relationships, and source text are selected to form the final context.
The context can be returned to the application or passed to a language model. Query settings can control the number of chunks, entities, seeds, and relationship included in the context.
Generate the Answer
After ranking the results, GraphRAG selects relevant information to assemble the context for answer generation. Depending on the search settings, the context contains source text and may also include graph information, such as entity descriptions.
GraphRAG sends the assembled context to a language model, which uses the information to generate an answer.
GraphRAG Example
Consider the question:
Who is the spouse of the author of Young Man Luther?
The graph connects the following facts extracted from two source chunks:
Young Man Luther --written by--> Erik Erikson --husband of--> Joan Erikson
The retrieval flow is:
- The question is converted into an embedding.
- Vector similarity search identifies relevant chunks and relationships. Matching relationships and chunks provide starting points for graph traversal.
- Graph traversal expands from these starting points to discover connected information about the book, Erik Erikson, and Joan Erikson.
- Results are ranked using graph scores for GRAPH searches or Reciprocal Rank Fusion (RRF) to combine graph and direct vector rankings for HYBRID searches.
- The selected supporting information is assembled into the context.
- When answer generation is requested, a language model uses this context to generate the answer.
A vector search might retrieve the chunk describing Young Man Luther because it mentions the book named in the question. The chunk identifying Joan Erikson as Erik Erikson’s spouse does not mention the book or identify Erik Erikson as its author, so it might rank too low to be retrieved. Graph traversal provides another way to discover this supporting information by following graph connections to Erik Erikson.