Tables
Use tables to define the structure for your data.
You can load new data into your tables or reference data in an existing location. You can define fine-grained access control permissions on tables by creating table permissions. For more information, see Table Permissions.
To share a table, see Share Data.
Tables can either be managed or external.
Managed Tables
A managed table defines a structure for data that's stored within AI Data Platform and can only be accessed by AI Data Platform users.
When you delete a managed table, the table definition and the table data are deleted.
External tables
An external table defines a structure for data that's stored in a location not managed by Oracle AI Data Platform. When you create an external table in AI Data Platform, the metadata life cycle is managed by AI Data Platform. When you delete an external table, only the table definition is deleted. The data referenced by the external table isn't deleted.
Ensure your users have the following IAM policies required to create external tables:
allow group <GroupName> to read buckets in compartment id <external-data-CompartmentId>
allow group <GroupName> to inspect objects in compartment id <external-data-CompartmentId>
Additional IAM policies are required for external tables. For more information, see IAM Policies for Oracle AI Data Platform.
Supported Table Formats
Tables can use file-based formats such as CSV, JSON, Avro, Parquet, and ORC, or transactional table formats such as Delta and Apache Iceberg. Iceberg tables use the Hadoop catalog implementation to manage table metadata in Oracle Cloud Infrastructure Object Storage.
| Format | Description | Usage |
|---|---|---|
| Comma-separated values (CSV) | Data is stored as a text file with a specified row-based file format to structure the data. Typically, the first row in the file is a header row that contains columns names for the data. | Used to exchange tabular data between systems. Each row in the file is a row in a table. |
| JavaScript Object Notation (JSON) | Data is stored in a standard text-based format for representing structured data based on JavaScript object syntax. JSON supports lists of objects or hierarchical structures. | Used in stream applications. JSON simplifies the storage of related data with complex relationships in a single document and avoids chaotic list conversion to a relational data model. Note that JSON isn't splittable. |
| Avro | Data is stored in a row based binary format while the schema is stored in JSON format to minimize file size and maximize efficiency. Avro has reliable support for schema evolution by managing added, missing, and changed fields. This lets old software read new data, and new software read old data. Also known as the data serialization system. | Used for data storage as Avro files are splittable and compressible. The serialized row-based storage is ideal for heavy write transactions, such as inserting data into AI Data Platform. Avro is also a good choice when schema evolution is critical during high speed writes. |
| Parquet | Data is stored in a columnar data format and is highly compressible and splittable. Parquet is optimized for the paradigm Write Once Read Many (WORM). It writes slowly but reads incredibly quickly, especially when you only access a subset of columns. | Used for solving Big Data problems as compression algorithms work better with columnar data format. You can store Big Data in various formats, such as images, videos, documents, and structured data tables. Parquet is a good choice for heavy workloads when reading portions of data. For example, when the dataset has many columns, but you only want to access a subset of columns. Ideal when you're dependent on Spark or when you want several services to access the same data stored in Object Storage. |
| Optimized Row Columnar (ORC) | Data is stored in collections of rows in a single file in columnar format. | Used for parallel processing of row collections across a cluster. Ideal when read transactions are more than write transactions or when compression is priority. |
| Delta lake | Data is stored in a columnar format that extends Parquet data files with a JSON file-based transaction log for ACID transactions and scalable metadata handling. | Used for transaction support. |
| Iceberg | An open table format that manages Parquet data files through versioned metadata, manifests, and snapshots. AI Data Platform uses the Iceberg Hadoop catalog implementation. | Use for ACID transactions, concurrent reads and writes, schema and partition evolution, time-travel queries, row-level updates, upserts, and snapshot management. |
Supported Data Types
| Data Type | Description |
|---|---|
| ByteType | Represents 1-byte signed integer numbers. The range of numbers is from -128 to 127. |
| ShortType | Represents 2-byte signed integer numbers. The range of numbers is from -32768 to 32767. |
| IntegerType | Represents 4-byte signed integer numbers. The range of numbers is from -2147483648 to 2147483647. |
| LongType | Represents 8-byte signed integer numbers. The range of numbers is from -9223372036854775808 to 9223372036854775807. |
| FloatType | Represents 4-byte single-precision floating point numbers. |
| DoubleType | Represents 8-byte double-precision floating point numbers. |
| DecimalType | Represents arbitrary-precision signed decimal numbers. Backed internally by java.math.BigDecimal. A BigDecimal consists of an arbitrary precision integer unscaled value and a 32-bit integer scale. |
| StringType | Represents character string values. |
| VarcharType(length) | A variant of StringType which has a length limitation. Data writing will fail if the input string exceeds the length limitation. |
| CharType(length) | A variant of VarcharType(length) which is fixed length. Reading column of type CharType(n) always returns string values of length n. Char type column comparison will pad the short one to the longer length. |
| BinaryType | Represents byte sequence values. |
| BooleanType | Represents boolean values. |
| DateType | Represents values comprising values of fields year, month and day, without a time-zone. |
| TimestampType | A timestamp with local time zone(TIMESTAMP_LTZ). It represents values comprising values of fields year, month, day, hour, minute, and second, with the session local time-zone. The timestamp value represents an absolute point in time. |
| TimestampNTZType | A timestamp without time zone(TIMESTAMP_NTZ). It represents values comprising values of fields year, month, day, hour, minute, and second. All operations are performed without taking any time zone into account. |
| YearMonthIntervalType(startField, endField) | Represents a year-month interval which is made up of a contiguous subset of MONTH, months within years [0..11] and YEAR, years in the range [0..178956970]. |
| DayTimeIntervalType(startField, endField) | Represents a day-time interval which is made up of a contiguous subset of SECOND, seconds within minutes and possibly fractions of a second [0..59.999999], MINUTE, minutes within hours [0..59], HOUR, hours within days [0..23] and DAY, days in the range [0..106751991]. |
| ArrayType(elementType, containsNull) | Represents values comprising a sequence of elements with the type of elementType. containsNull is used to indicate if elements in a ArrayType value can have null values. |
| MapType(keyType, valueType, valueContainsNull) | Represents values comprising a set of key-value pairs. The data type of keys is described by keyType and the data type of values is described by valueType. For a MapType value, keys aren't allowed to have null values. valueContainsNull is used to indicate if values of a MapType value can have null values. |
| StructType(fields) | Represents values with the structure described by a sequence of StructFields (fields). |
| StructField(name, dataType, nullable) | Represents a field in a StructType. The name of a field is indicated by name. The data type of a field is indicated by dataType. nullable is used to indicate if values of these fields can have null values. |
Limitations
The following limitations apply to tables in AI Data Platform:
- You can't define an external table on any data files or directories within or on a volume.
- You can't define an external table on a bucket or its directory that's already used for another external table or external volume
- Views can't be viewed or listed in the Master Catalog.
Schema Evolution
Schema evolution in Oracle AI Data Platform allows users with the required permissions to update a managed table using SQL in a notebook.
This is useful when a table definition changes over time to support new columns, removed columns, renamed columns, partition changes, or table renames without recreating the dataset from scratch. The supported formats are Parquet, Avro, Delta, and Iceberg.
Supported Operations
The following schema evolution operations were analyzed for managed tables:
| Operation | Delta | Parquet | Avro | Iceberg |
|---|---|---|---|---|
| Rename table | Supported | Supported | Supported | Supported |
| Add columns | Supported | Supported | Supported | Supported |
| Drop columns | Supported | Not supported | Not supported | Supported |
| Alter or rename columns | Supported | Not supported | Not supported | Supported |
| Replace columns | Supported | Not supported | Not supported | Supported |
| Add partitions | Partitions are created automatically when data is written. You can't add individual partitions through DDL. | Supported through DDL | Supported through DDL | Partitions are created automatically when data is written. You can't add individual partitions through DDL. You can add fields to the partition specification using ALTER TABLE ... ADD PARTITION FIELD.
|
| Drop partitions | Remove the relevant data and run VACUUM.
|
Supported | Supported | You can't drop individual partitions through DDL. Delete the relevant rows instead. You can remove fields from the partition specification using ALTER TABLE ... DROP PARTITION FIELD.
|
| Change data type | May require a CTAS or overwrite-schema workaround. | Not supported | Not supported | Supported only for compatible type promotions, such as INT to BIGINT, FLOAT to DOUBLE, and increasing decimal precision through ALTER TABLE. Narrowing and incompatible conversions aren't supported.
|
Create a Managed Table
You can create a managed table to hold structured data for schema you manage.
- Open the Create table dialog.
- From the left navigation pane:
- Click
 Create and select Table.
- In the Select table location dialog, select the catalog and schema you want to create the table for, and click Select.
- Click
- From
 Master catalog:
- In the Master catalog tree or the Catalogs tab, click the catalog you want to create the table for to open it.
- In the Schemas tab, click the schema you want to create the table for to open it.
- Click Add to schema and select Table.
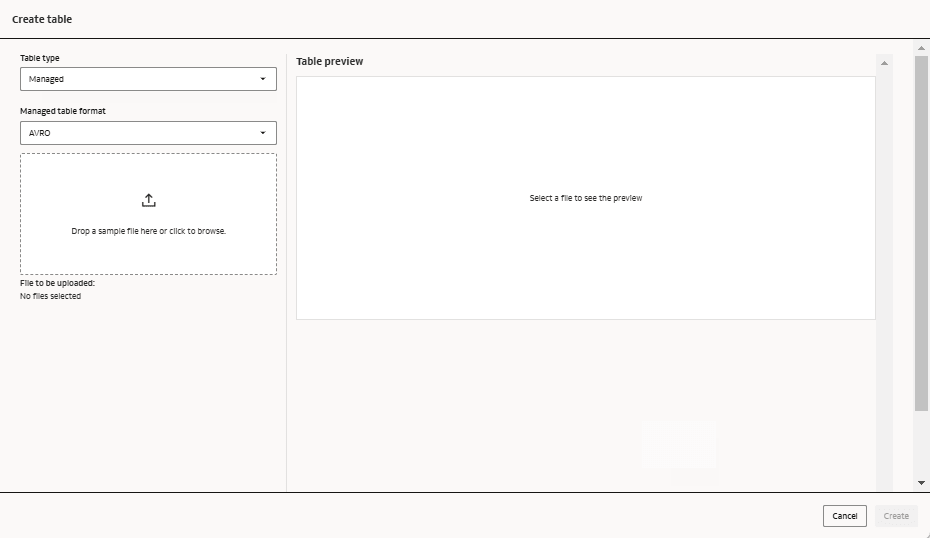
- From the left navigation pane:
Create an External Table
You can create an external table to query data directly in OCI Object Storage without moving or duplicating the data in Oracle AI Data Platform.
- Open the Create table dialog.
- From the left navigation pane:
- Click Create and select Table.
- In the Select table location dialog, select the catalog and schema you want to create the table for, and click Select.
- Click
- From Master catalog:
- In the Master catalog tree or the Catalogs tab, click the catalog you want to create the table for to open it.
- In the Schemas tab, click the schema you want to create the table for to open it.
- Click Add to schema and select Table.
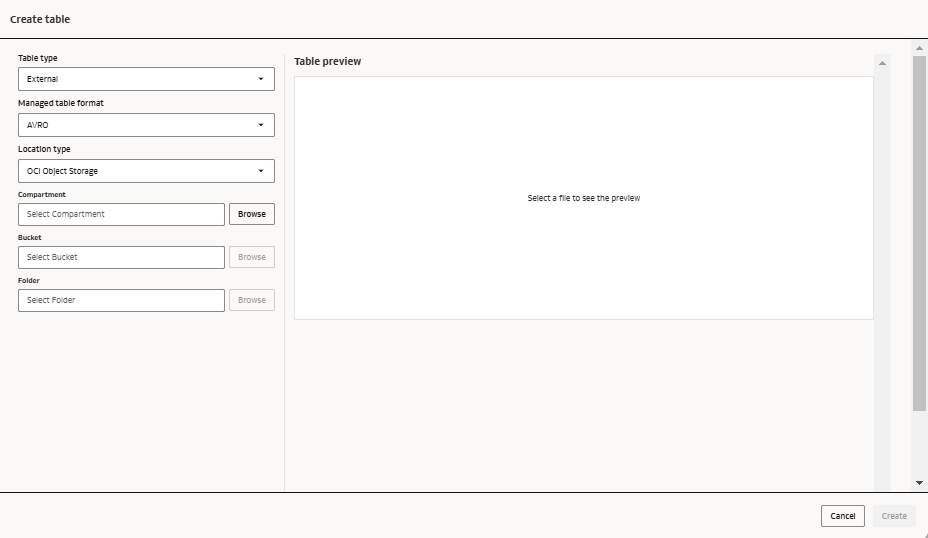
- From the left navigation pane:
View Table Details
You can view the details of a table to review its configuration and metadata.
The Details tab for a table displays the table key, type, and format, along with when and by whom the table was created and last updated. It also displays the table properties.
- In the left navigation pane, click Master catalog.
- In the Master catalog tree, expand the catalog and schema that contain the table you want to view, then click Tables.
- In the Tables tab, locate your table and click
 Actions, then click View.
- Click Details.
Rename a Table
You can rename a table that you manage if its contents or purpose has changed.
Note:
Edits to external tables in Oracle AI Data Platform aren’t pushed to the remote catalog in OCI Object Storage.- In the left navigation pane, click Master catalog.
- In the Master catalog tree, expand the catalog and schema that contain the table you want to edit, then click Tables.
- In the Tables tab, locate your table and click Actions, then click Rename.
- Edit the table name and press Enter.
Edit a Table Description
You can modify the description of a table you manage if its contents or purpose has changed.
Note:
Edits to external tables in Oracle AI Data Platform aren't pushed to the remote catalog in OCI Object Storage.- In the left navigation pane, click Master catalog.
- In the Master catalog tree, expand the catalog and schema that contain the table you want to edit, then click Tables.
- In the Tables tab, locate your table and click Actions, then click Edit description.
- Edit the table description and click Save.
Delete a Table
You can delete a table from a schema you manage when it's no longer needed.
Note:
The data in OCI Object Storage referenced by an external table isn't deleted.- In the left navigation pane, click Master catalog.
- In the Master catalog tree, expand the catalog and schema that contain the table you want to delete, then click Tables.
- In the Tables tab, locate your table and click Actions, then click Delete.
- Click Delete.